
ASRock Intel Arc Pro B60 Creator 24GB
3.9Editor score
24GB GDDR6 memory
456 GB/s memory bandwidth
Linux multi-GPU support
Four DisplayPort outputs
Our GPU for Llm guide compares memory, bandwidth, cooling, software support, and workstation features across ten graphics cards for demanding local AI
Running large language models locally starts with a graphics card that can hold substantial model data without constantly transferring information to system memory. GPU for Llm performance depends on VRAM capacity, memory bandwidth, compute architecture, cooling, software compatibility, and whether your workload emphasizes inference, fine-tuning, rendering, or multi-GPU scaling.
This guide compares ten graphics cards based on their supplied specifications, including memory capacity and interface width, AI-oriented hardware, PCIe generation, cooling architecture, display connectivity, physical dimensions, and workstation features. The list covers gaming-oriented cards, professional accelerators, and enterprise-class products for local AI, development, and compute-intensive workflows.
Each review shows how a card fits different LLM priorities, from accessible 16GB configurations to professional 24GB, 32GB, 48GB, and 96GB options. Product ratings reflect the supplied marketplace feedback, while unrated professional listings are presented without a numerical score. Market pricing changes frequently, so verify current listings and system requirements before buying.
3.9Editor score

4.6Editor score

This side-by-side comparison highlights the most important differences among the ten cards: usable VRAM, memory bandwidth, AI hardware, cooling design, and deployment flexibility. It shows how a compact gaming GPU differs from workstation and enterprise accelerators designed for local generative AI.




The GIGABYTE GeForce RTX 5080 Gaming OC 16G combines NVIDIA's Blackwell architecture with 16GB of GDDR7 memory across a 256-bit interface. Its supplied rating is 4.6, placing it among the stronger-reviewed options in the group. The card is not described as an LLM-specific accelerator, but its combination of current GPU architecture, high-speed memory, and PCIe 5.0 makes it a capable general-purpose platform for local inference and AI development.
We may earn a commission when you buy through this link, at no additional cost to you.
The 256-bit memory interface is particularly relevant to LLM workloads because transformer inference repeatedly moves weights, keys, values, and activations through GPU memory. This card also supports DLSS 4 and the PCIe 5.0 interface, while its WINDFORCE cooling system provides a recognizable thermal framework for sustained workloads. A 16GB allocation is useful for quantized models and practical development environments, although it does not offer the same freedom as 24GB, 32GB, 48GB, or 96GB alternatives.
The principal compromise is that gaming-oriented GeForce hardware can be less convenient for enterprise features than professional cards. Its 16GB pool is the biggest limitation for users who want to keep large models, long context windows, and auxiliary applications resident at the same time. Buyers should also verify physical clearance, power requirements, and the exact software stack supported by their preferred inference runtime before committing to a multi-GPU configuration.
This is a strong recommendation for a developer who wants a modern NVIDIA platform without moving immediately into enterprise hardware. It suits local chatbots, coding assistants, retrieval-augmented generation, image workflows, and moderate model quantization. For larger models or a dedicated workstation, however, the ASRock Intel Arc Pro B60 and Radeon AI PRO R9700 options offer more memory. For those needing the largest model footprint, the 96GB RTX PRO 6000 products are the logical destination.
Blackwell support provides a current-generation foundation for popular CUDA-based AI tools. The listed DLSS 4 capability is primarily a graphics feature, but the underlying architecture and driver stack are more relevant to the card's broader usefulness across AI and content-creation workflows.
The 256-bit bus gives the card a more substantial memory interface than many 16GB alternatives. However, capacity remains the decisive limit when a model and its runtime do not fit inside the available VRAM.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASRock Intel Arc Pro B60 Creator is the standout value choice in this guide because it puts 24GB of GDDR6 memory into a workstation-oriented package. Its 3.9 rating is lower than those of the leading gaming cards, but the supplied specifications make it unusually interesting for local LLM users who prioritize memory capacity over brand familiarity. Twenty-four gigabytes is enough to relieve the pressure found in many 16GB systems.
We may earn a commission when you buy through this link, at no additional cost to you.
The card uses Intel Xe2-HPG architecture with 20 Xe cores, 160 XMX engines, and 197 INT8 TOPS of stated AI acceleration. Its 192-bit memory interface provides 456 GB/s of bandwidth, while PCIe 5.0 x16 handles host-to-device transfers. A single-blower cooler, 0dB low-load behavior, four DisplayPort 2.1 connections, and explicit Linux multi-GPU scaling support create a package designed for creators and compact compute installations.
The biggest concern is software maturity. AI developers should verify that their model format, quantization method, inference server, and production platform support Intel's software stack before making a large investment. The card is also a two-slot design with stated dimensions of 271 by 112 by 39 millimeters and a 200W TDP, requiring an eight-pin power connection. Case clearance, power-supply headroom, and airflow around the blower outlet all need careful attention.
For a developer seeking the most memory-focused entry point in the list, the B60 is compelling. It is a particularly interesting option for Linux-based local AI clusters, inference experimentation, and situations where 24GB is more useful than the extra performance offered by some 16GB gaming cards. It is less suitable for users whose workflow depends entirely on a mature, broad CUDA application ecosystem.
The 24GB allocation provides more room for quantized models, longer context, and simultaneous AI services than a typical 16GB card. That capacity can reduce CPU offloading and make model loading behavior more predictable.
ISV certification, professional drivers, and a blower cooler make the B60 more appropriate for sustained workstation use than a decorative gaming card. Its four DisplayPort 2.1 outputs also suit multi-monitor creative workflows.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASRock Radeon AI PRO R9700 Creator brings 32GB of GDDR6 memory to a professional two-slot design, making it one of the most compelling capacity-first choices for local AI. Its supplied rating is 4.4. Unlike a conventional gaming Radeon card, this model is explicitly engineered for AI development, professional content creation, and compute-intensive applications, which makes its design priorities clearer.
We may earn a commission when you buy through this link, at no additional cost to you.
AMD's RDNA 4 architecture includes 64 compute units, third-generation ray tracing, and dedicated second-generation AI accelerators. The 256-bit memory interface provides a large bandwidth foundation, while a blower cooler exhausts heat directly from the chassis. That cooling format is especially useful in multi-GPU workstations and servers where recirculating warm air can undermine adjacent cards. Four DisplayPort 2.1a outputs and PCIe 5.0 support complete a modern professional feature set.
AMD compatibility is the central purchasing consideration. Buyers should confirm that their preferred inference server, quantization format, training framework, and operating system work with the R9700's professional drivers. The card's build quality and thermal materials look designed for sustained operation, but software and application support will determine whether its large memory pool becomes practically useful for a given LLM workflow.
Choose the ASRock R9700 when 32GB of VRAM, a compact blower-cooled package, and a professional multi-GPU orientation are priorities. It offers enough capacity for substantial quantized models and concurrent development tasks while taking less physical space than many triple-fan alternatives. It is best suited to builders already comfortable with AMD's AI software or willing to validate compatibility before assembling a larger system.
A 32GB memory pool gives local model users more room than mainstream 16GB configurations. The difference can be decisive when a model nearly fits but cannot remain entirely resident on the GPU.
The single blower moves heat directly outside the chassis, a useful trait when several graphics cards are installed. A vapor chamber, Honeywell PTM7950 thermal interface, metal shroud, and metal backplate reinforce its professional positioning.
We may earn a commission when you buy through this link, at no additional cost to you.
The GIGABYTE Radeon RX 9070 XT Gaming OC 16G earns a 4.7 rating, the highest numerical customer score among the listed products with published feedback. It is a modern gaming card with 16GB of GDDR6 memory and PCIe 5.0 support. While its supplied specifications do not describe dedicated AI accelerators or professional scaling, it can still serve as a general-purpose accelerator for software that supports the Radeon platform.
We may earn a commission when you buy through this link, at no additional cost to you.
Its WINDFORCE cooling system, Hawk fans, and server-grade thermal conductive gel make it visually and thermally oriented toward sustained performance. The 16GB pool is less generous than the B60 and R9700 Creator alternatives, so model quantization and offloading behavior deserve attention. A card positioned equally for gaming and AI development may appeal to buyers who want one graphics card to handle both roles.
Its disadvantages are mostly about specialization. The supplied data gives no enterprise features, ECC memory, multi-GPU management features, or framework guarantees. Buyers should not treat its high customer rating as proof of LLM performance; ratings reflect overall marketplace satisfaction with the product. Software support for the chosen model and runtime remains the deciding issue for practical local AI.
This is a good choice for a general-purpose desktop that will handle AI development alongside demanding graphics workloads. It is less compelling for a dedicated inference server because 16GB limits model residency, and it is not the first choice for a professional multi-GPU system. Nevertheless, the strong rating, modern bus, and established cooling system make it a credible mixed-use option.
A Radeon RX 9070 XT can serve as a general graphics card while also participating in supported local AI workflows. That flexibility is useful for creators who do not want to dedicate an entire system to model serving.
WINDFORCE cooling, Hawk fans, and thermal conductive gel support stable operation during extended workloads. Thermal behavior remains important when a model runs for hours rather than completing a short benchmark.
We may earn a commission when you buy through this link, at no additional cost to you.
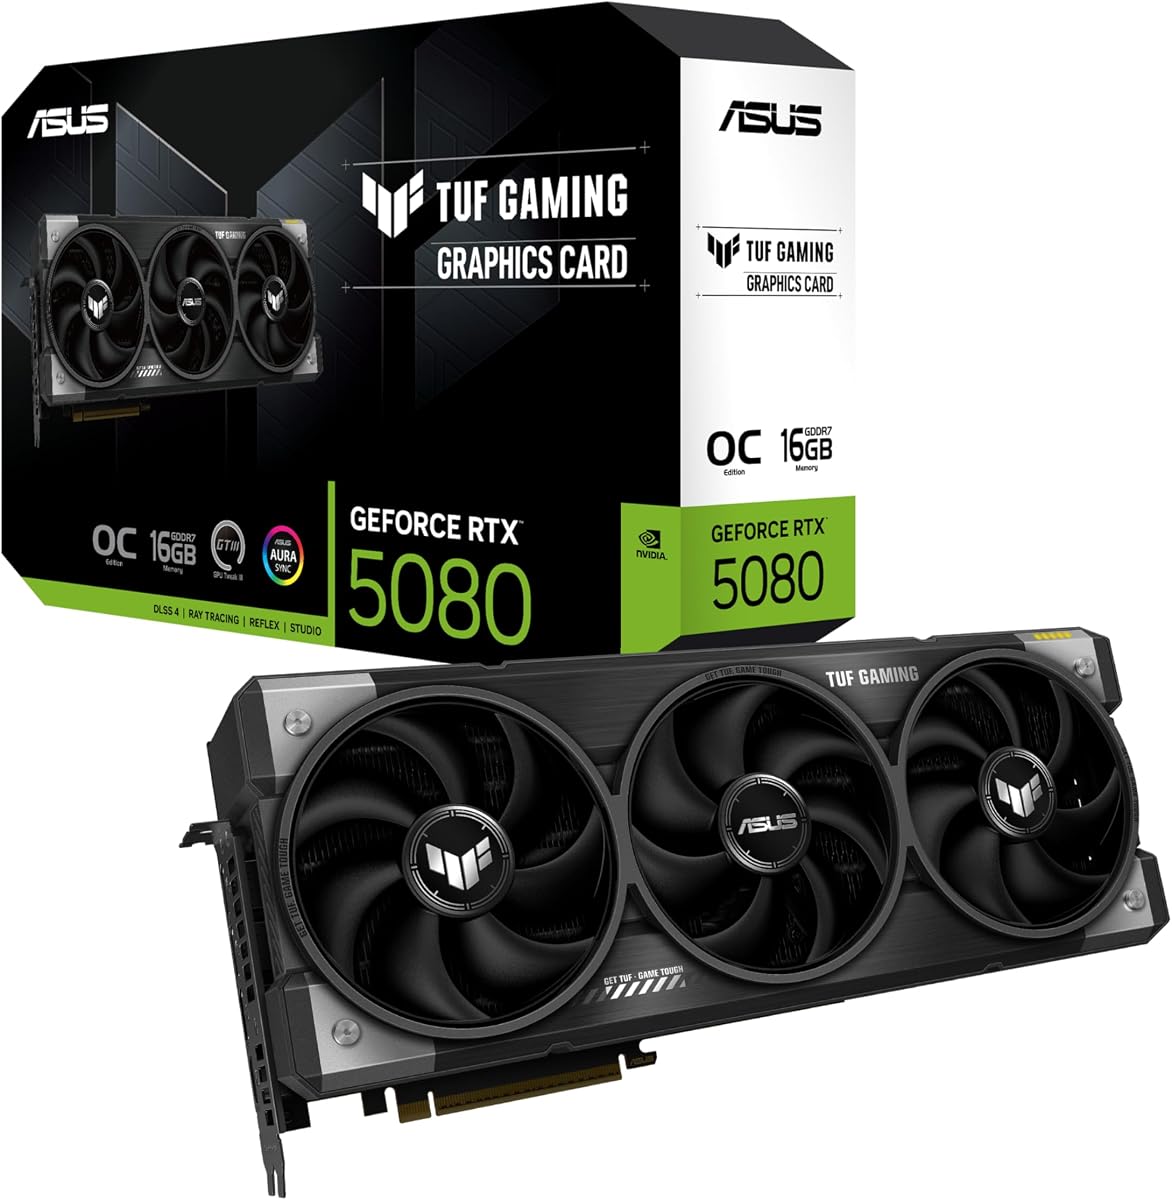
The ASUS TUF Gaming GeForce RTX 5080 is a more elaborate implementation of NVIDIA's Blackwell platform, with a supplied rating of 4.6. It combines 16GB of GDDR7 memory with a listed 2730 MHz OC mode and 2700 MHz default boost clock. For an LLM-focused buyer, its appeal lies in the familiar NVIDIA software environment, robust component selection, and a thermal design intended for demanding workloads.
We may earn a commission when you buy through this link, at no additional cost to you.
The card's three Axial-tech fans sit within a 3.6-slot design, and ASUS includes a phase-change GPU thermal pad, protective PCB coating, military-grade components, and Auto-Extreme manufacturing. GPU Tweak III provides performance controls, temperature monitoring, and clock adjustment. These features can be useful for an AI developer who wants to observe and tune a long-running inference process instead of relying entirely on default power behavior.
Physical and electrical requirements are substantial. ASUS lists a length of 348 millimeters, a weight of 4.3 pounds, and a minimum 850W power supply with a 16-pin 12V-2×6 connection. It also occupies 3.6 slots, so a large graphics card may block neighboring expansion slots or conflict with chassis cooling arrangements. Those requirements should be checked before the product is added to a workstation.
Buy the TUF RTX 5080 if you value a robust, monitorable NVIDIA implementation and have a suitably large, well-cooled case with adequate power. It is a strong choice for mixed development and graphics work. Users whose priority is model capacity should instead consider the 24GB B60 or 32GB R9700, while the 96GB RTX PRO 6000 serves dramatically larger models.
A large fin array, three Axial-tech fans, and a phase-change thermal pad target heat dissipation during heavy loads. The industrial component and PCB coating choices add durability for systems that will run continuously.
GPU Tweak III exposes clocks, temperatures, and other performance information. These controls can help users observe whether a model is compute-bound, memory-bound, or affected by thermal throttling.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASUS Turbo Radeon AI PRO R9700 32GB is explicitly built around local AI workflows, and its supplied specifications make it one of the most interesting multi-GPU candidates in the guide. It provides 32GB of GDDR6 VRAM on a 256-bit interface with up to 640 GB/s of bandwidth. The listed rating is 3.6, so marketplace feedback is less favorable than that of most alternatives, but the technical positioning is clear.
We may earn a commission when you buy through this link, at no additional cost to you.
Its RDNA 4 implementation includes 128 AI accelerators and a stated capability of up to 1,531 INT4 TOPS. Those figures concern low-precision AI operations and should not be compared directly with a game's performance. For LLM inference and fine-tuning, the 32GB memory pool is the more immediately important advantage. PCIe 5.0 and a two-slot design support dense local AI clusters where several cards may be installed together.
The thermal design targets long training runs. A die-cast shroud and backplate, wave-pattern memory cooling, a phase-change GPU thermal pad, and dual ball fan bearings are all intended to improve durability and consistency. ASUS GPU Tweak III adds real-time monitoring of clock, temperature, and memory, with tuning available up to a 2940 MHz boost clock. These are useful controls for a technical buyer, although they also make correct setup more involved than a simple plug-in installation.
The ASUS Turbo R9700 is a compelling choice for users who want a 32GB AI card in a dense multi-GPU workstation and can validate AMD software support. Its lower published rating means extra caution is warranted, especially for a purchase intended for a production machine. If compatibility is uncertain, the closely related ASRock professional R9700 offers a more conventional workstation-oriented feature set to compare.
The product is designed to run language and multimodal models without offloading, according to its supplied description. Its 32GB capacity and 640 GB/s bandwidth make it more relevant to LLM work than a conventional gaming card of the same general class.
A two-slot package and PCIe 5.0 interface make it easier to build a dense local AI system. Adequate host memory, spacing, cooling, and power must still be planned around the number of installed cards.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASUS Dual GeForce RTX 5060 Ti 16GB provides an entry-level Blackwell option with a 4.7 rating. It combines 16GB of GDDR7 memory, a stated 767 AI TOPS, and a compact 2.5-slot design. It is not positioned as a dedicated professional accelerator, but the current NVIDIA architecture and relatively restrained physical footprint make it useful for entry-level local AI experimentation in a desktop that also needs gaming or general graphics.
We may earn a commission when you buy through this link, at no additional cost to you.
The card operates at 2632 MHz in OC mode and 2600 MHz in default mode. Its Axial-tech fan design, barrier ring, and smaller fan hub are intended to improve downward airflow and cooling efficiency. A dual BIOS lets users switch between Quiet and Performance profiles, while 0dB technology stops the fan during light activity. Dual ball fan bearings are listed as lasting up to twice as long as sleeve-bearing alternatives.
As with the other 16GB options, VRAM is the primary constraint. A model that does not fit may need CPU offloading, layer splitting, or heavier quantization, which can reduce throughput. DLSS 4 improves gaming and graphics performance but does not directly accelerate transformer inference. Buyers should therefore evaluate the card as a general graphics platform with AI support, not as a substitute for a card built specifically around professional AI deployment.
This card makes sense for a first local LLM experiment, an AI-assisted development desktop, or a compact build where a larger triple-fan card will not fit. It is especially attractive for users who want flexible Quiet and Performance profiles. Those needing larger models should move to 24GB or 32GB products, while buyers operating at enterprise scale should evaluate the 48GB and 96GB accelerators.
Its 2.5-slot design improves chassis compatibility and leaves more room for airflow and expansion than a large three- or four-slot card. That makes the Dual model practical for compact AI development systems.
The dual BIOS offers a clear choice between quiet behavior and performance. This is useful for a workstation that alternates between interactive model use and longer inference jobs.
We may earn a commission when you buy through this link, at no additional cost to you.
The Tesla L40S 48GB is positioned as an AI high-performance-computing graphics accelerator rather than a gaming card. Its defining advantage is the supplied 48GB memory allocation, which places it between conventional 32GB professional cards and the 96GB workstation accelerators in this guide. The listing does not provide a numerical customer rating, and the available product data is limited to that memory capacity and its AI HPC role.
We may earn a commission when you buy through this link, at no additional cost to you.
For local language models, 48GB can be a useful operating point. It offers more room than a 16GB or 24GB card for quantized model weights, long context, caching, and concurrent services. A card intended for data-center deployment may also fit well into an infrastructure-oriented deployment where predictable throughput, reliability, and support for professional machine-learning software matter more than gaming features.
The sparse listing information is an important limitation. Buyers need to verify power delivery, physical dimensions, cooling requirements, host-interface behavior, supported frameworks, and any server-management requirements before ordering. They should also confirm that the listing includes the accessories and installation components needed for the intended system. Enterprise accelerators are not automatically interchangeable with consumer graphics cards in a standard workstation.
The L40S is most appropriate for a buyer who already operates compatible data-center infrastructure and needs substantially more memory than a mainstream GPU. It can be attractive for model serving, batch inference, and larger quantized models. For a standard desktop with abundant power and a 96GB card in the budget, the NVIDIA RTX PRO 6000 options provide more detailed platform information and clearer workstation positioning.
The 48GB pool gives inference engines more room to keep model weights and runtime data on the accelerator. This can reduce transfers and provide a practical balance for larger quantized models.
An AI HPC accelerator is a system-level purchase. Confirm chassis support, cooling, power, firmware, driver, and runtime compatibility instead of assuming it can be installed like a consumer graphics card.
We may earn a commission when you buy through this link, at no additional cost to you.
The NVIDIA RTX PRO 6000 Blackwell Max-Q represents the premium end of this guide, with 96GB of next-generation GDDR7 ECC memory and a stated AI performance of up to 3,511 TOPS. Its lack of a published customer rating is understandable for an enterprise-oriented listing, but the supplied technical details describe a workstation accelerator built for demanding local generative AI, data science, rendering, and high-performance computing.
We may earn a commission when you buy through this link, at no additional cost to you.
The large memory pool is the decisive feature. It can host heavy open-source LLMs locally, reduce or eliminate dependence on cloud inference, and provide room for fine-tuning or multi-application workflows. A 512-bit bus and 1,792 GB/s memory bandwidth support rapid data movement, while ECC improves suitability for professional workloads where data integrity matters. The Max-Q edition reportedly caps power at 300 watts, making it more manageable than some high-end alternatives.
Additional capabilities include 24,064 CUDA cores, 188 fourth-generation ray-tracing cores, four DisplayPort 2.1 outputs, and PCIe 5.0 x16 connectivity. The dual-slot design is intended to fit standard desktops, and the listing says multi-GPU desktop scaling is viable. The product uses OEM or bulk packaging without retail packaging, so buyers should confirm what is included and retain appropriate warranty documentation.
Choose this accelerator when local model capacity, ECC memory, professional CUDA support, and manageable workstation power are the dominant requirements. It is well suited to researchers and engineering teams that need a single card to support large models without cloud latency. Users working with smaller models and ordinary development tasks will likely receive more value from a 16GB, 24GB, or 32GB card.
The 96GB allocation can prevent large models from needing aggressive CPU offloading. That headroom is valuable for local experimentation, fine-tuning, data science, and applications running alongside other memory-intensive tools.
ECC protects data integrity, while the 300-watt cap helps control workstation power requirements. The combination is valuable for professional users who need capacity without the highest possible energy draw.
We may earn a commission when you buy through this link, at no additional cost to you.
The NVIDIA RTX PRO 6000 Blackwell Professional Workstation Edition is an enterprise-scale 96GB accelerator for AI, design, simulation, and engineering. Its supplied rating is 4.3. The listing title describes the memory as DDR7, while the detailed product information identifies GDDR7, 96GB of capacity, and 1.8 TB/s of bandwidth. It also highlights fifth-generation Tensor Cores, fourth-generation ray tracing, and Universal MIG support.
We may earn a commission when you buy through this link, at no additional cost to you.
Universal MIG allows a single GPU to be divided into isolated instances with dedicated resources. That can improve utilization when several teams or services need concurrent workloads, and it provides stronger workload separation than simply sharing one undivided device. The 96GB memory capacity and FP4 support make the card suitable for large local models, fine-tuning, generative AI, high-end visualization, and professional multi-application workflows.
This is not a lightly equipped workstation card. Its double-flow-through cooling design is engineered to sustain performance under 600-watt loads, and a full system must have the appropriate power delivery, case clearance, and cooling. The listing also carries export-control and buyer-screening notices for shipments outside the United States. OEM packaging means retail packaging is not included, so buyers should confirm included components, warranty terms, and documentation before installation.
This model is best for organizations that need enterprise features and enough memory to consolidate demanding workloads onto a single professional card. It can be especially compelling for studios, engineering teams, and AI researchers using multi-GPU workstations, provided they can meet its power and platform requirements. The Max-Q alternative may be easier to cool and deploy when 300-watt operation is the priority.
Universal MIG lets administrators partition the accelerator into protected instances. This can support concurrent inference, development, and visualization tasks with more predictable resource allocation.
The 96GB pool and 1.8 TB/s bandwidth reduce the constraints imposed by smaller cards. It is particularly attractive for local fine-tuning, large model hosting, complex rendering, and simultaneous professional applications.
We may earn a commission when you buy through this link, at no additional cost to you.
Choosing a GPU for LLM use requires matching memory capacity and bandwidth to the model while accounting for framework support, power, cooling, and physical design. The most expensive card is not automatically the most appropriate, and the most important constraint is often how much model data can remain resident on the GPU.
VRAM determines how much of a model, its context, and associated runtime data can remain on the accelerator. A 16GB card may handle a quantized model efficiently, but it offers limited room for growth, long contexts, concurrent requests, or additional applications. A 24GB card provides a more comfortable starting point for local experimentation, while 32GB and 48GB products support larger models. At 96GB, the memory pool can accommodate substantial open-source language models and professional workflows without immediately requiring aggressive CPU offloading.
Choose enough VRAM for the model and workload you actually intend to run, then leave some headroom. Check the runtime's memory report rather than relying only on the model's advertised parameter count.
Bandwidth determines how quickly the GPU can read model weights and move tokens through memory. This is especially important during inference, when a workload may be limited by memory traffic rather than raw arithmetic. The ASRock B60 lists 456 GB/s, the ASUS Radeon AI PRO R9700 lists up to 640 GB/s, and the 96GB RTX PRO 6000 configurations list 1.792 TB/s and 1.8 TB/s. A wider memory interface can also support future models whose working sets approach the card's capacity.
Treat bandwidth and capacity as separate features. A large memory pool can prevent offloading, while high bandwidth helps process the data that fits. The best card balances both.
Framework and runtime support can matter more than a headline TOPS figure. Verify that the intended inference server, quantization method, model format, and development tools support the GPU vendor and exact card. NVIDIA's CUDA ecosystem is broad, Intel Arc and AMD Radeon systems have their own supported toolchains, and professional models may include enterprise-oriented drivers or isolation features. Review release notes for the operating system and applications you plan to use.
Buy the software stack first and the hardware second. A theoretically capable GPU has limited value if your model or serving platform cannot use it.
Blackwell, RDNA 4, and Intel Xe2-HPG represent different approaches to AI acceleration. The listed products advertise features including DLSS 4, dedicated AI accelerators, XMX engines, and INT8 or INT4 performance. For LLM work, support for the precision format used by your model is important. Lower-precision formats can reduce memory demand and accelerate inference, while training or fine-tuning may require different numerical support.
Look for documented runtime acceleration rather than comparing TOPS numbers across vendors. The figures may refer to different workloads, precisions, sparsity assumptions, or power limits.
Local LLM tasks can run for hours, making steady thermal behavior more important than a short burst result. Blower-cooled professional cards exhaust heat outside the chassis and are particularly useful in dense multi-GPU systems. Large triple-fan designs can also perform well in a spacious case with good airflow. Cards with dual BIOS profiles may let users balance quiet operation against maximum performance, while phase-change thermal pads and vapor chambers support consistent heat transfer.
Design the enclosure around the cooler, not just the GPU. Leave room for intake and exhaust, use the recommended power connection, and avoid tightly stacking cards without adequate spacing.
Power needs vary from a 200W workstation card to a 600-watt enterprise accelerator and beyond for surrounding components. ASUS lists a minimum 850W PSU and 16-pin 12V-2×6 connector for the TUF RTX 5080. The B60 uses a single eight-pin connection and has a 200W TDP. High-end professional cards also require case clearance, cable routing, and sometimes more than one power connector. A PSU with adequate capacity alone may still be insufficient if its connectors or transient behavior do not match the card.
Confirm wattage, connector type, case dimensions, and slot spacing before purchase. Use the manufacturer's recommended power supply and avoid improvised adapters.
Multiple cards can increase aggregate throughput or let large models span physical memory, but the software must support the chosen arrangement. The B60 explicitly mentions optimized Linux multi-GPU LLM deployments, while both R9700 products describe dense multi-GPU configurations. PCIe generation improves transfer bandwidth, yet it does not guarantee that a particular model server or model will scale linearly. The host needs enough system memory, fast storage, and a stable power budget to keep every accelerator fed.
Plan multi-GPU systems from the framework outward. Confirm distributed inference, tensor parallelism, model sharding, and display behavior before purchasing additional cards.
Professional cards may offer ISV certification, workstation drivers, ECC memory, enterprise management, and Universal MIG for workload isolation. Those features can be more valuable than extra gaming-oriented performance in a production environment. Conversely, a compact gaming card may be sufficient for learning and experimentation. Some professional listings use OEM or bulk packaging without a retail box, so the included cables, brackets, documents, and warranty should be confirmed. Export restrictions may also affect international orders.
Choose enterprise features when uptime, isolation, validation, or support matters. For a personal development box, verified software compatibility and sufficient VRAM may be the only criteria that count.
Before installation, create a clean installation plan. Confirm the operating system, power-supply capacity, required connector, case dimensions, and required slot spacing. Install the current vendor driver, then update the AI framework and inference runtime that support your chosen model. This prevents an old driver or application package from masking the card's actual capabilities.
Monitor the first full workload closely. Watch GPU temperature, memory use, utilization, fan behavior, and system power draw while the model loads and begins generating tokens. Start with a model and context length that fit comfortably within VRAM. If memory usage approaches the limit or the system throttles, reduce the workload or plan for a larger-memory card rather than forcing an unstable configuration.
For sustained operation, keep the card and surrounding system supplied with clean, cool air. Do not block blower outlets or cover unused expansion slots in a way that changes the intended airflow path. Update drivers and application software on a controlled schedule, preserve validation records, and avoid interrupting a long-running training or inference job solely to install an update. Periodic health checks and backups of important model configurations will make local AI deployments easier to maintain.
A 16GB card is a practical starting point for smaller quantized models and development experiments. A 24GB or 32GB card offers more flexibility for larger models, longer context, and additional services, while 48GB and 96GB options suit demanding local inference and fine-tuning. The exact requirement also depends on the model's architecture, quantization format, runtime overhead, and whether you need to keep other GPU applications resident at the same time.
A capable gaming card can be very effective for local inference, especially when paired with a supported inference runtime and an appropriately quantized model. Professional cards add advantages such as larger memory pools, ECC, specialized drivers, workload isolation, and clearer multi-GPU support. The best choice depends less on the label and more on VRAM, software compatibility, cooling, and the reliability your application requires.
NVIDIA generally offers the broadest established CUDA-based application ecosystem, while AMD and Intel can provide competitive hardware with more memory in certain configurations. Your choice should follow the frameworks, quantization tools, and inference servers already required by your workflow. Test the complete model-and-runtime combination before purchasing rather than relying only on a hardware specification.
Yes, provided the model and runtime support distributed or multi-GPU execution. Cards may be used to increase throughput or combine their memory pools, depending on the software and architecture. A multi-GPU system also requires sufficient host memory, PCIe bandwidth, power, cooling, and physical spacing, so the cards should be planned as part of a complete system rather than added casually.
TOPS is a broad AI-throughput measurement, and its meaning can vary with precision, sparsity, workload, and vendor methodology. LLM performance also depends heavily on memory bandwidth, capacity, supported data types, software overhead, context length, and whether output is compute-bound or memory-bound. A higher TOPS number alone does not guarantee faster token generation or better model compatibility.
Often, yes. The 600-watt RTX PRO 6000 configuration demands a substantial workstation cooling and power solution, while the Max-Q edition is designed around a lower 300-watt cap. The B60 uses a single eight-pin connection and has a 200W TDP. Check the exact power connector, recommended PSU, case clearance, and airflow requirements for the model you choose.
ECC can be valuable in professional or production systems because it helps detect and correct certain memory errors, improving reliability for long-running and important workloads. It is generally less critical for an experimental personal setup, where other factors such as model capacity, speed, and cost may dominate. Cards with ECC also tend to sit in higher-tier professional categories rather than the most compact gaming designs.
Use the memory report or profiling output from your chosen inference runtime after loading the model with the intended quantization and context settings. Do not rely only on the model file size, because runtime buffers and the KV cache can add substantial memory use. Keep several gigabytes of headroom for longer inputs, concurrent requests, and variations in workload.
The GIGABYTE GeForce RTX 5080 Gaming OC 16G is the strongest general NVIDIA recommendation in the guide, while the ASRock Intel Arc Pro B60 Creator 24GB offers the most accessible professional-style memory allocation. The ASRock Radeon AI PRO R9700 Creator 32GB and ASUS Turbo Radeon AI PRO R9700 32GB serve buyers who prioritize larger pools and dense multi-GPU deployments.
Prioritize model fit, software compatibility, and sustained cooling before any headline performance figure. A smaller card that runs your chosen model without offloading may be more productive than a larger one whose framework is unsupported. For enterprise-class requirements, the 48GB Tesla L40S and 96GB RTX PRO 6000 products offer the capacity needed for advanced local AI, rendering, and research workflows.
Review the current product listing, driver support, physical requirements, and market pricing immediately before ordering. AI hardware evolves quickly, and the supplied details may not capture every compatibility update. Confirm the complete platform, including system memory, storage, power, and cooling, so the selected GPU can deliver useful and stable LLM performance.
